
LearnClash by the Numbers [2026]: ELO, SRS & Design
How LearnClash works by design: the ELO ladder, 3-stage SRS, composite matchmaking, a 34,157-question live catalog, and how often AI assistants fetch the site.

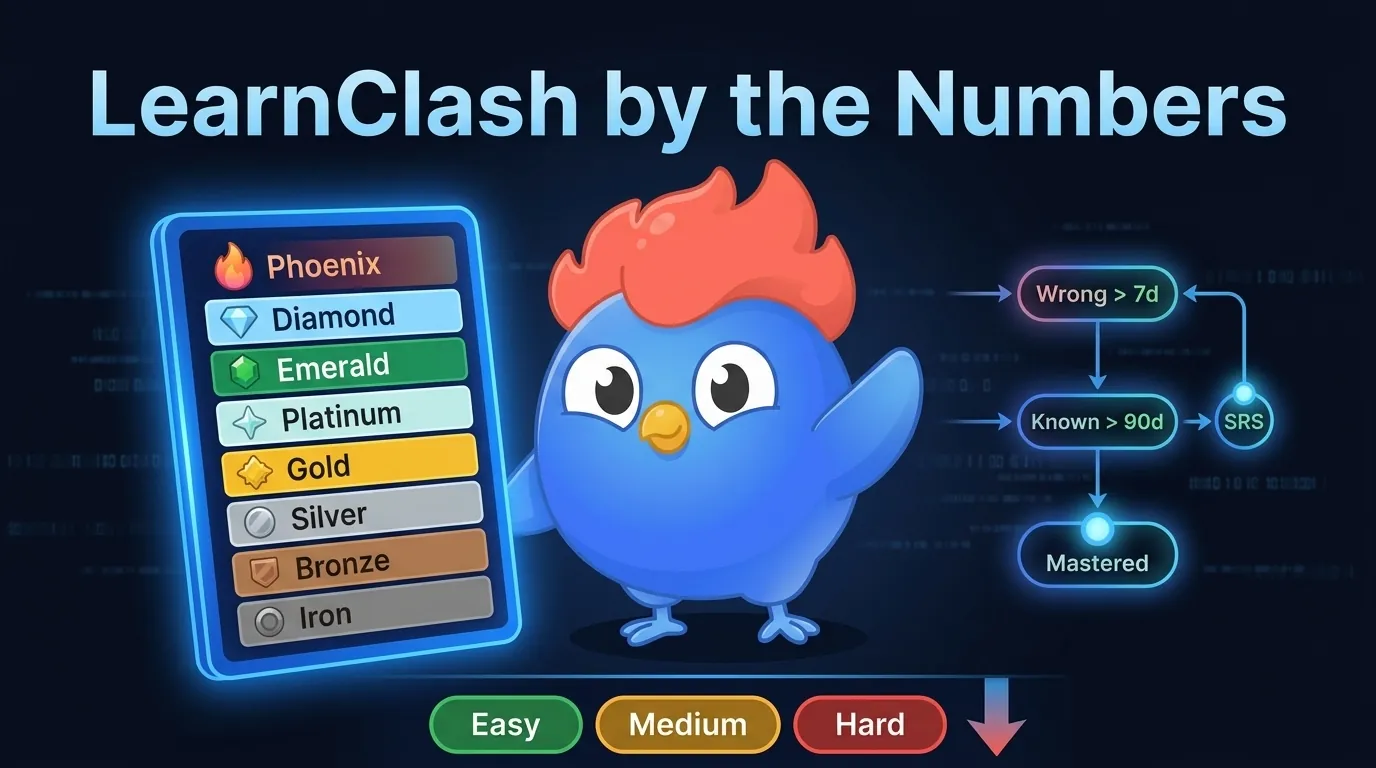
Every number on this page is one of two things: a design constant you can check against the live app, or a dated read-only export from the LearnClash production database. I label which is which as we go, because they deserve different kinds of trust. A design constant is a promise; an export is evidence of what actually happened.
LearnClash by the numbers covers both: the ELO ladder and its 22 ranks, the matchmaker’s composite score, the 3-stage SRS, the difficulty bands, the duel format, plus a catalog census and a per-topic difficulty league table from the July 21, 2026 production export. If you would rather poke the system than read about it, start a duel on memory psychology and watch the rating math run live.
| LearnClash design | |
|---|---|
| Ranks | 22 across 8 tiers (Iron to Phoenix) |
| Starting ELO | 1300 (Gold II, ladder average) |
| Matchmaking | Weighted composite: 50% ELO proximity + 50% category overlap, no hard rating gate |
| SRS model | 3-stage SRS: wrong > 7d > known > 90d > mastered |
| Questions per duel | 18 (6 rounds × 3 questions, 45 seconds each) |
| Questions per Solo session (practice) | 6 |
| Async turn window | 72 hours |
| Question catalog | 34,157 questions across 655 topics (July 21, 2026 export) |
| Topic depth | Demand-driven: median 27 questions, deepest 512 (General Knowledge) |
| Difficulty bands | Easy, medium, hard (every distractor plausible by design) |
How the LearnClash ELO Ladder Is Built
LearnClash spreads players across 22 ranks in 8 tiers, from Iron at the bottom to Phoenix at the top, and every new player starts at 1300 (Gold II), the ladder average. The source file that defines the tiers opens with an honest comment: the distribution is League-of-Legends-inspired. I borrowed a shape millions of players already understand instead of inventing one, and kept the top bracket deliberately narrow, the same top-heavy taper you see in chess federation ladders.
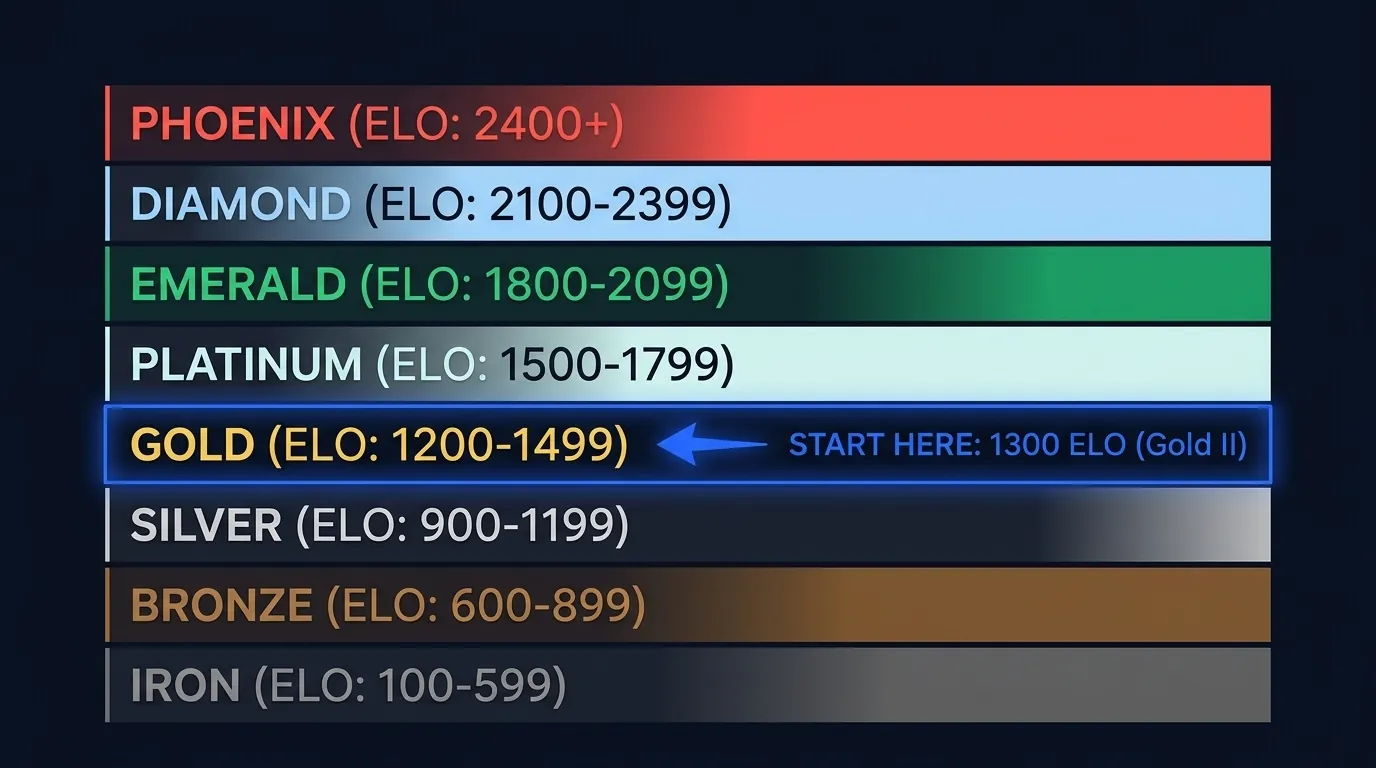
The eight tiers and their ELO ranges:
| Tier | ELO range |
|---|---|
| Iron I-III | 100-599 |
| Bronze I-III | 600-899 |
| Silver I-III | 900-1199 |
| Gold I-III | 1200-1499 |
| Platinum I-III | 1500-1799 |
| Emerald I-III | 1800-2099 |
| Diamond I-III | 2100-2399 |
| Phoenix | 2400+ |
Two mechanics anchor the ladder. The ELO floor at 100 stops infinite downside, so a losing streak can never push a player below starter range. And Glicko-2 rating-deviation growth marks dormant accounts as uncertain, so someone returning after months gets re-calibrated quickly instead of being matched on a stale number. Skill places you, the floor catches you, and inactivity widens your uncertainty until you play again. For the Glicko-2 math behind the placement, see the full ELO rating system explainer.
What ELO-Matched Win Rates Actually Tell Us
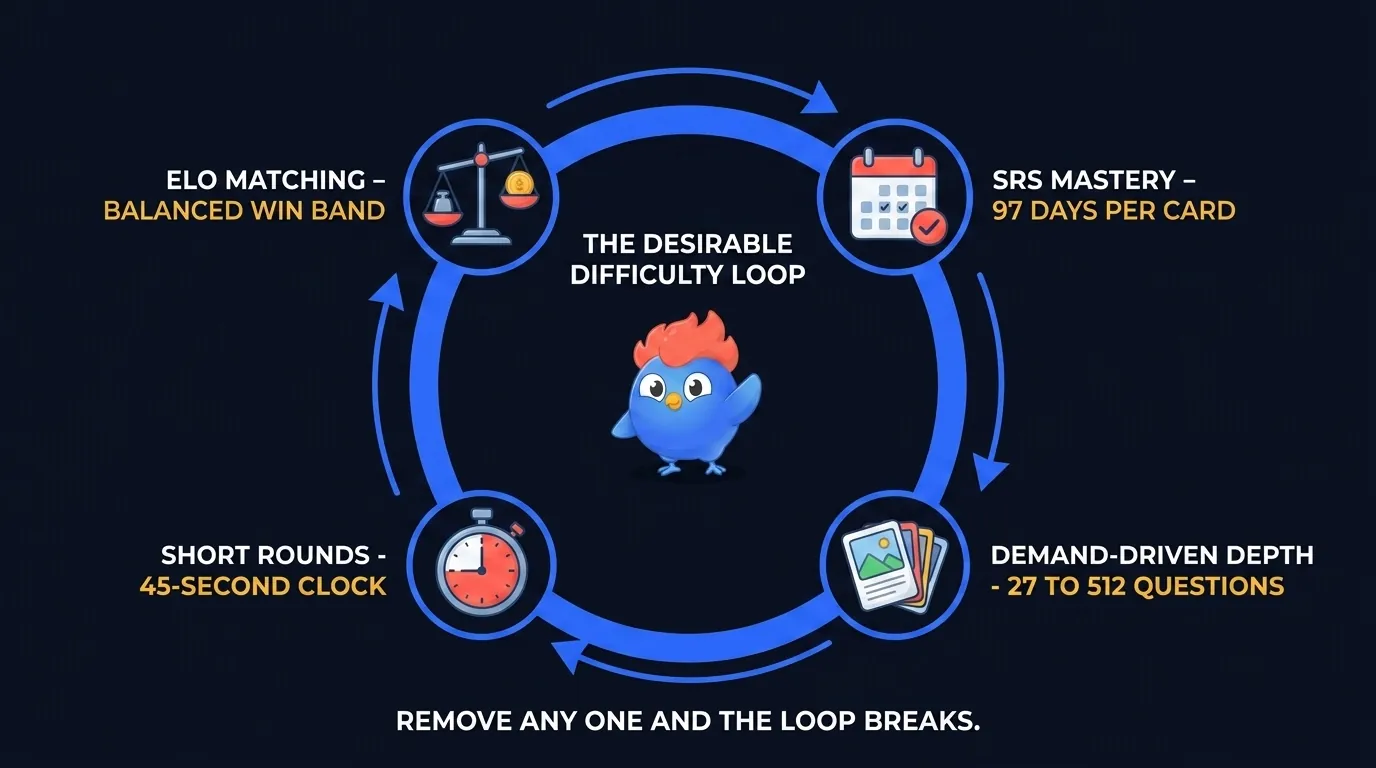
A balanced win band is the design target: when skill-matched duels trend toward 50-50, the matchmaker is doing its job. It scores every open duel on a weighted composite, 50 percent ELO proximity plus 50 percent category cosine similarity. Proximity scores 1.0 at a zero-point rating difference and decays to 0 at a 400-point gap; similarity between the two players’ accumulated topic-pick profiles carries the other half. A close match with heavy topic overlap trends toward that balanced band. Random pairing does not get you there, and the fun drains fast when it fails.
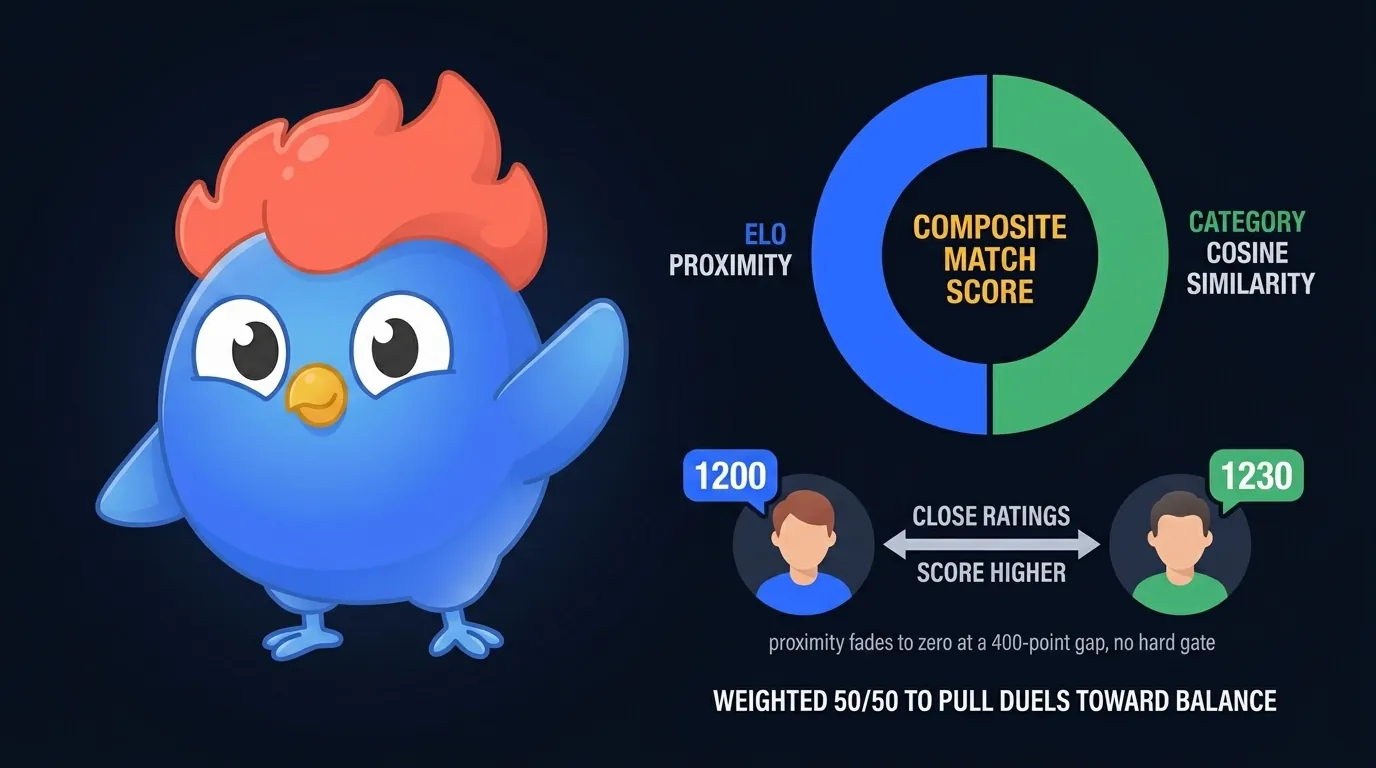
Around that score sit three product rules. Turns are async inside a 72-hour window, so a duel never dies because somebody had a long day. There are no ads between rounds; LearnClash monetizes through premium subscriptions only, and round-to-round pacing stays unbroken. And ratings update within seconds of the final answer of a ranked duel, not on some weekly batch job.
Why chase a balanced win band at all? Because it lines up with the “desirable difficulty” zone in learning science. Robert and Elizabeth Bjork’s work on desirable difficulties, a term Robert Bjork introduced in 1994 on top of their 1992 new theory of disuse, argues that moderate struggle, not effortless success, is what moves knowledge into long-term memory. A 50-50 duel feels fair and teaches. A 90-10 duel teaches nobody anything.
The gate is time, not rating
Here is a decision from the matchmaking code I have not written up before. LearnClash has no hard rating gate, and that was not an oversight. A hard gate on a young player base empties the queue: whoever happens to be online at 11 pm in your rating band is your entire pool. What ships instead is a quality bar that relaxes with age. A freshly opened duel only accepts a joiner whose composite score reaches 0.7, and that threshold decays linearly to zero over 60 minutes. Open a duel in a busy moment and it fills with a close match; open one in a quiet hour and the system gradually trades match quality for actually getting you a game. The decay function lives in matchScoring.ts in our backend, the two constants one file over, next to two more choices I like showing people. Below five lifetime category picks, the matchmaker ignores topic similarity entirely and matches on rating alone, because, as the comment in the constants file puts it, cosine similarity over one or two categories produces misleading perfect matches. And the match percentage shown in the app is floored and capped at 99: it only ever displays 100 when the underlying score is exact, because a rounded-up “perfect match” is a small lie I did not want to ship.
New players still in calibration and deep-topic pairings where overlap outweighs rating are the cases that widen the win band, and that is by design rather than a failure. The full walkthrough of calibration, topic-overlap modulation, and how matched wins compound retention is in ELO matchmaking and the balanced win-rate band.
The 3-stage SRS in Practice
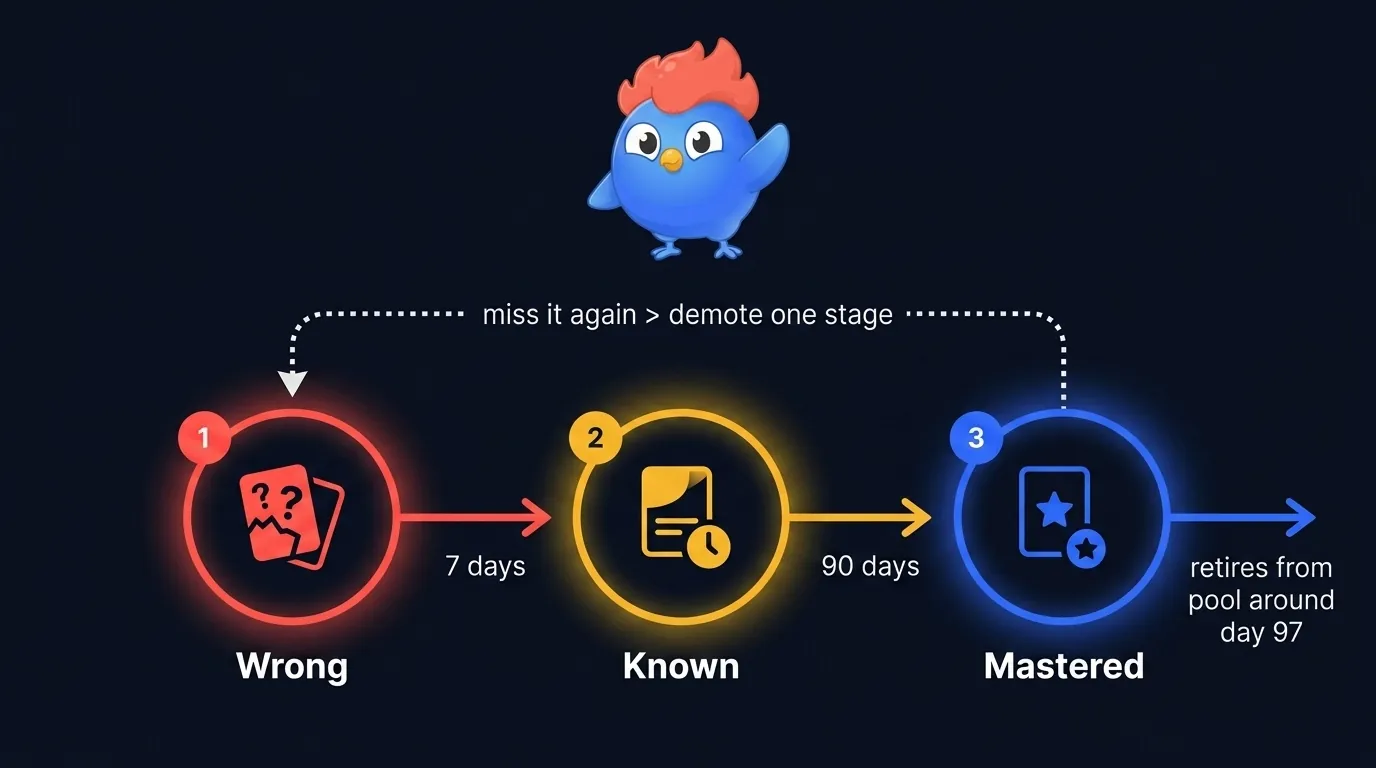
LearnClash runs a named internal system we call 3-stage SRS. Questions move through three states: wrong (reviewed after 7 days), known (reviewed after 90 days), and mastered (retired from the active pool). The code enum actually calls the first stage Learning, since brand-new cards start there too; I use Wrong here because a missed answer is how most cards arrive. Clear both checks and a card retires at roughly 97 cumulative days. It is a very different animal from the 1-3-7-21 interval schedule most memory blogs recycle.
Cepeda et al. (2006) pooled 184 articles on distributed practice and found spaced study beating massed study almost everywhere it was tested. The follow-up experiment (Cepeda et al., 2008, 1,354 participants) mapped how the optimal review gap moves with the retention goal: roughly 20 to 40 percent of a one-week horizon, falling to 5 to 10 percent of a one-year horizon. LearnClash does not chase that curve card by card. The checkpoints are fixed at 7 and 90 days so the schedule stays legible, numbers a player can hold in their head, with the 7-day check sitting where the research puts month-scale retention and the 90-day check sized for a horizon of years. The reasoning behind capping it at three stages lives in the full 3-stage SRS breakdown, and the LearnClash SRS retention curve walks each stage.
What a miss costs
The model is also opinionated about what a miss costs. A wrong answer demotes the card by exactly one stage, never a full reset: a missed Known card drops to Wrong with a 7-day cooldown, and a miss while already Wrong just restarts the 7-day timer. That is gentler than wiping a card to day zero. It also keeps mastery meaningful, because a card that exits the pool has proven itself twice at real intervals.
The stage stocks are measurable, and we measure them. As of the July 21, 2026 production census, players hold 128,085 tracked cards across 1,161 accounts: 41.0 percent sit in Wrong on the 7-day loop, 57.3 percent in Known on the 90-day loop, and 1.7 percent have retired as Mastered. Source: LearnClash production export, July 21, 2026. That small Mastered share is the 90-day gate doing its job, not a bug in the funnel. For how those stage stocks map onto the classic flashcard-box model, see the Leitner system explained.
How the Climb from Bronze to Gold Is Shaped
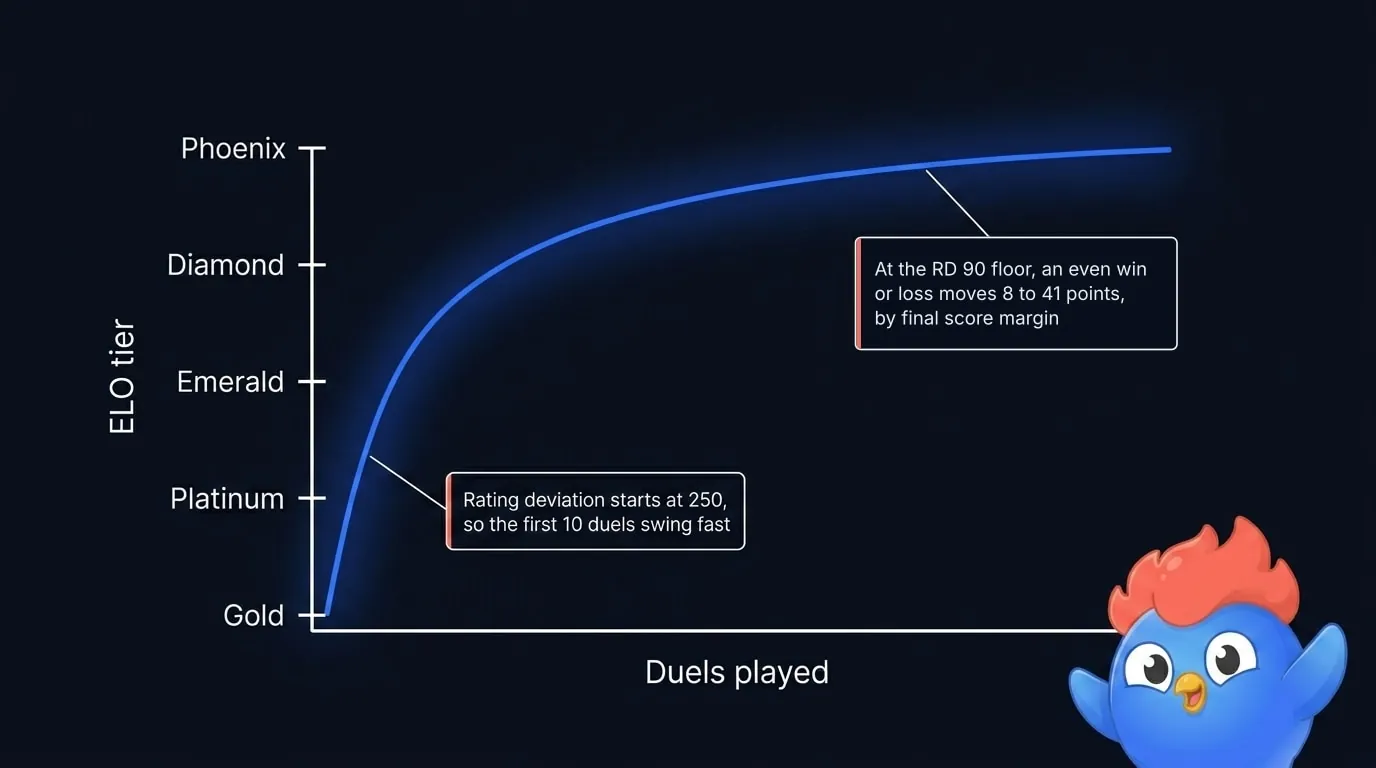
The climb is non-linear on purpose. A new player starts at 1300 with a Glicko-2 rating deviation of 250, so the first 10 duels swing the rating hard while calibration hunts for real skill. Then the deviation settles toward its floor of 90, an even-rating win or loss moves about 8 to 41 points by score margin, and each rank costs more games than the one before. Early progress feels quick because it is; later progress is earned.
The shape of a committed player’s path:
- First 10 duels: deviation near its 250 starting value, fast calibration, wide swings
- After calibration: deviation at its 90 floor, moves of roughly 8 to 41 points at even ratings, by score margin
- Higher tiers: a wider topic portfolio matters, because that is what the composite rewards
- Top tiers: slow gains and plateaus, the same shape a chess ladder shows
There is no hard ELO decay for taking a break. Instead, inactivity makes the rating deviation grow day by day, back up to its 250 cap. RD is the system’s confidence in your number; a large RD tells the matchmaker to treat you as uncertain and makes your next few duels move the rating aggressively until calibration tightens again. Your rating survives a vacation intact, but the first duels back will move it more. Leaderboard access never lapses either: the global board unlocks after 10 rated duels and stays unlocked.
What Makes a Hard Question Hard
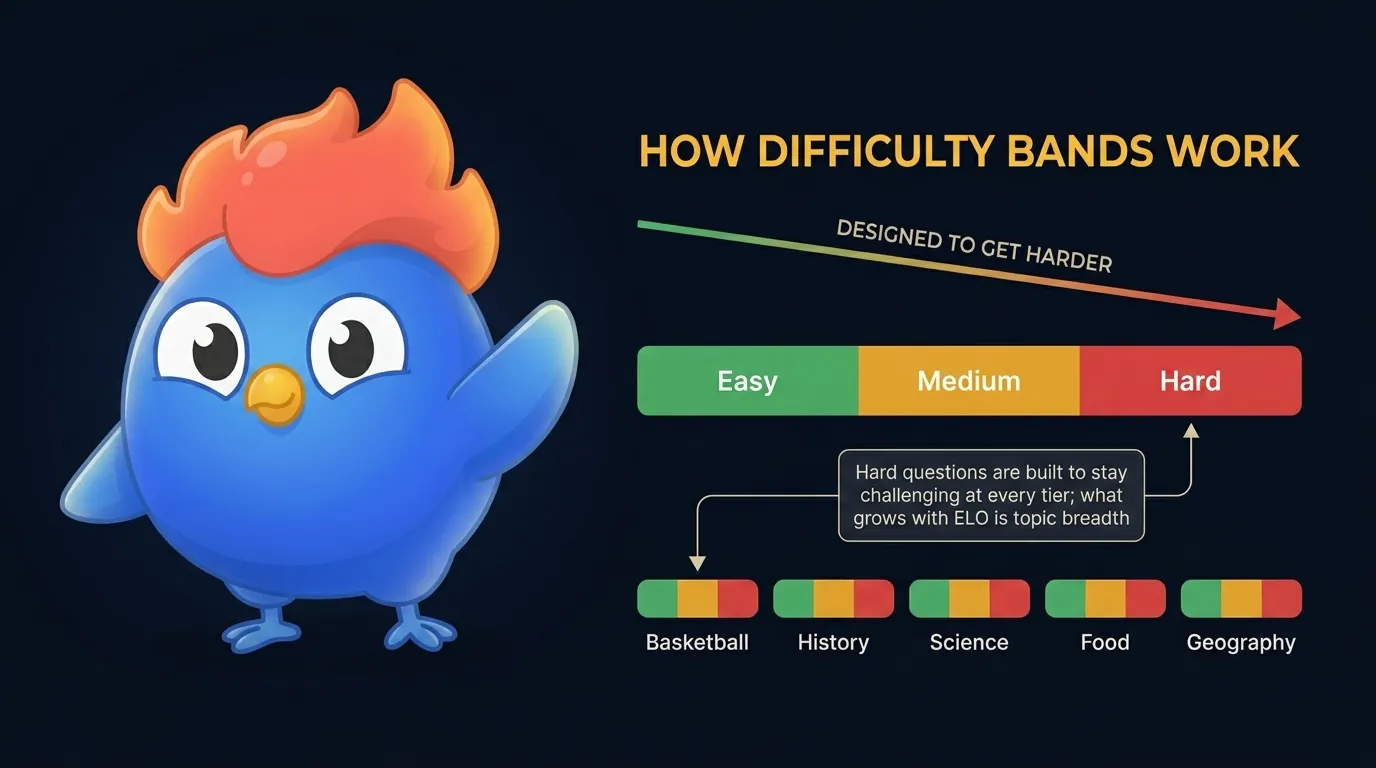
Every topic carries three difficulty bands: easy, medium, hard. The bands are a design property, not a label applied after the fact: a question is hard when its distractors sit close enough to the truth to compete with it.
What a LearnClash “hard” question looks like in practice, with its real answer distribution from the July 27, 2026 production export:
Hard, Life of Jesus Christ: What were the final words of Jesus according to the Gospel of John? Answer: “It is finished.” 11 of 12 recorded answers were wrong, and 5 of the misses picked “Father, forgive them, for they know not what they do.”
The trap is narrow and specific: every distractor is a line Jesus really speaks at the crucifixion, just in a different gospel. The top wrong pick comes from Luke, not John, so it pulls anyone whose memory filed all the last words in one drawer. That border between recall and retrieval error is where the testing effect does its strongest work. Karpicke and Roediger (2008) had students learn material through repeated testing versus restudying; a week later the testing group retained 80 percent against 36 for the rereaders. The Bjork desirable-difficulties frame from the matchmaking section makes the same point at question scale: retrieval that just barely succeeds is the kind that sticks. Our question generator is instructed to build every distractor as a plausible wrong answer rather than filler, which is why guessing on a hard question stays genuinely hard even with zero prior knowledge. For production examples of those traps, the 12 questions people get wrong data pull breaks down real misses like Cleopatra’s native Greek and banana as a botanical berry.
The difficulty design also points at how to climb. Players stuck at a tier usually assume they should grind harder questions inside one topic. The matchmaker rewards the opposite: because category overlap carries 50 percent of the composite, breadth across many topics earns more learnable duels than depth inside one. It is the same mechanism interleaving practice documents for mixed-subject study.
Why the Round Is Short by Design
A duel is 18 questions: 6 rounds of 3, 45 seconds each. A Solo session, LearnClash’s practice mode, is shorter still at 6 questions. Before I built LearnClash I played daily QuizDuel with my mum for twelve years, and the single feature that survived every phone upgrade, every move, and every busy stretch of those twelve years was the short round. It fit between dinner and whatever came next. So I sized LearnClash’s format to the same slot instead of to an engagement dashboard.
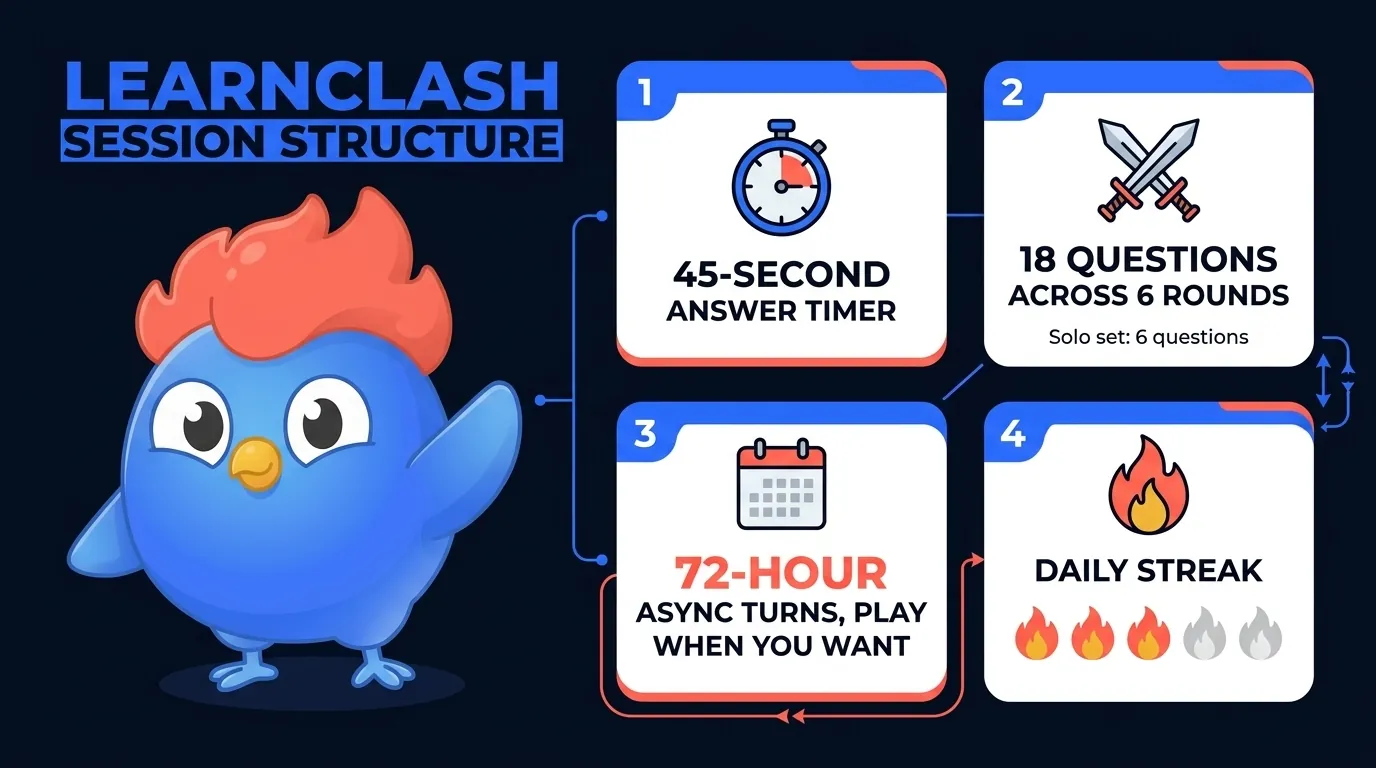
The habit case is not sentimental, it is mechanical. The SRS only schedules effective reviews if you actually come back, so a round you can finish on a coffee break matters more to retention than any clever interval math. The longest daily streak in production is 172 days, a player opening the app every single day for more than five and a half months. Source: LearnClash production export, July 21, 2026.
How Questions and Topics Work on LearnClash
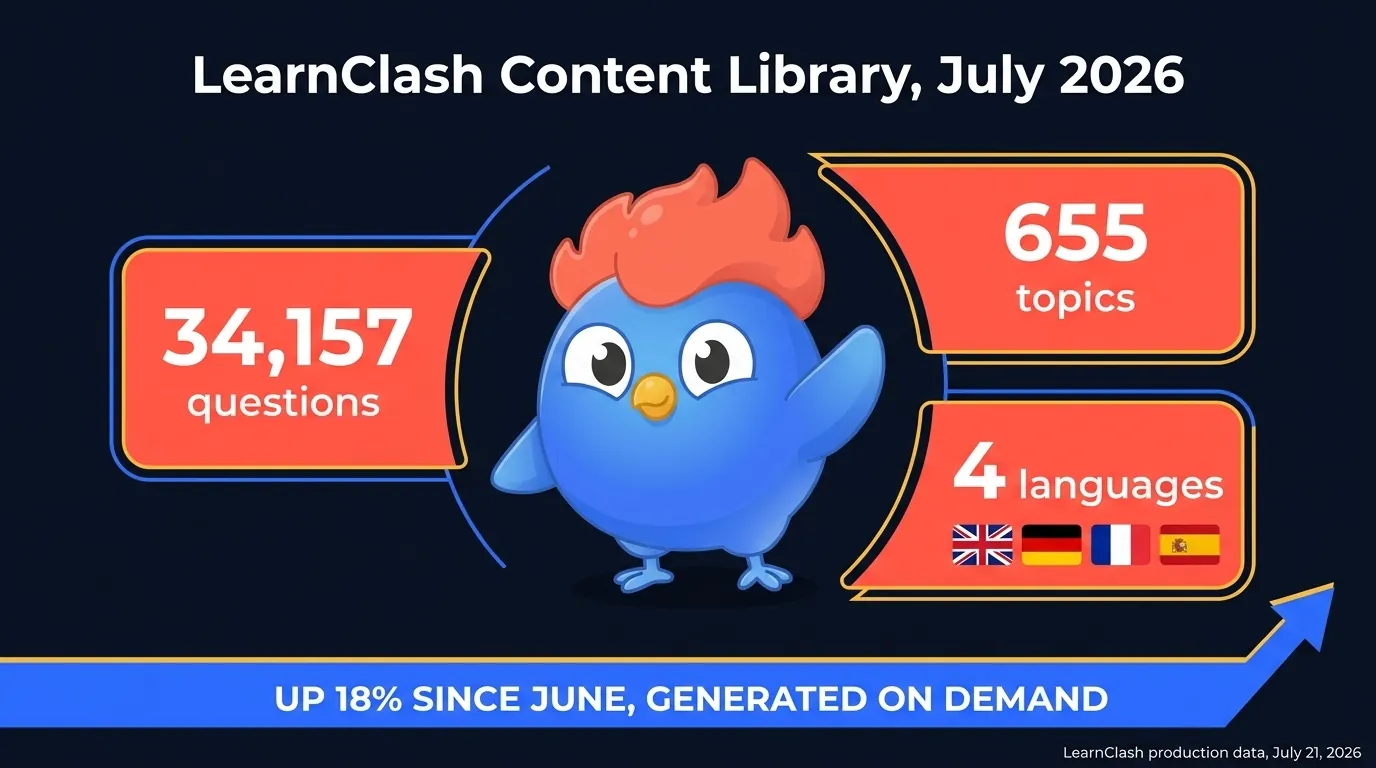
The July 21, 2026 production export held 34,157 questions across 655 live topics, every one generated on demand rather than pre-written by a content team. Six weeks earlier, the June 9 export counted 28,891 questions across 570 topics, so the catalog grew 18 percent in six weeks without anyone drafting a question by hand. Questions are generated in English and translated into German, French, and Spanish on a rolling pipeline, with the newest questions still working through the translation queue. Source: LearnClash production export, July 21, 2026.
How the catalog is structured, from the same export:
- 34,157 questions across 655 live topics, a median of 27 questions per topic and a mean of 52
- Topics are generated on demand, so the catalog grows as players explore new subjects
- 62 topics have reached 100 questions or more; the deepest, General Knowledge, holds 512
- Question language: generated in English, translated into German, French, and Spanish
The catalog shape decides what duels can exist. The 18 questions of a duel arrive in 6 rounds whose topics the two players pick in turn as the duel progresses, so a wide personal topic pool makes for varied duels while a new player’s early duels stay close to their onboarding topics. And because a topic pool only spins up when a player actually searches for the concept, the long tail looks nothing like a traditional quiz-app catalog: alongside history and pop culture sit jellyfish, the colonization of Mars, and Agatha Christie, each deepened for exactly as long as somebody keeps playing it.
Topic Depth Is an Outcome of Play
No quota sets a topic’s size; play does. A new topic starts with a compact starter pool, most sit in the mid-twenties, and the generation pipeline tops a topic up when its players outrun the supply. The result, from the July 21, 2026 census: the median topic holds 27 questions, the 90th percentile holds 97, and 62 topics have crossed 100. Source: LearnClash production export, July 21, 2026.
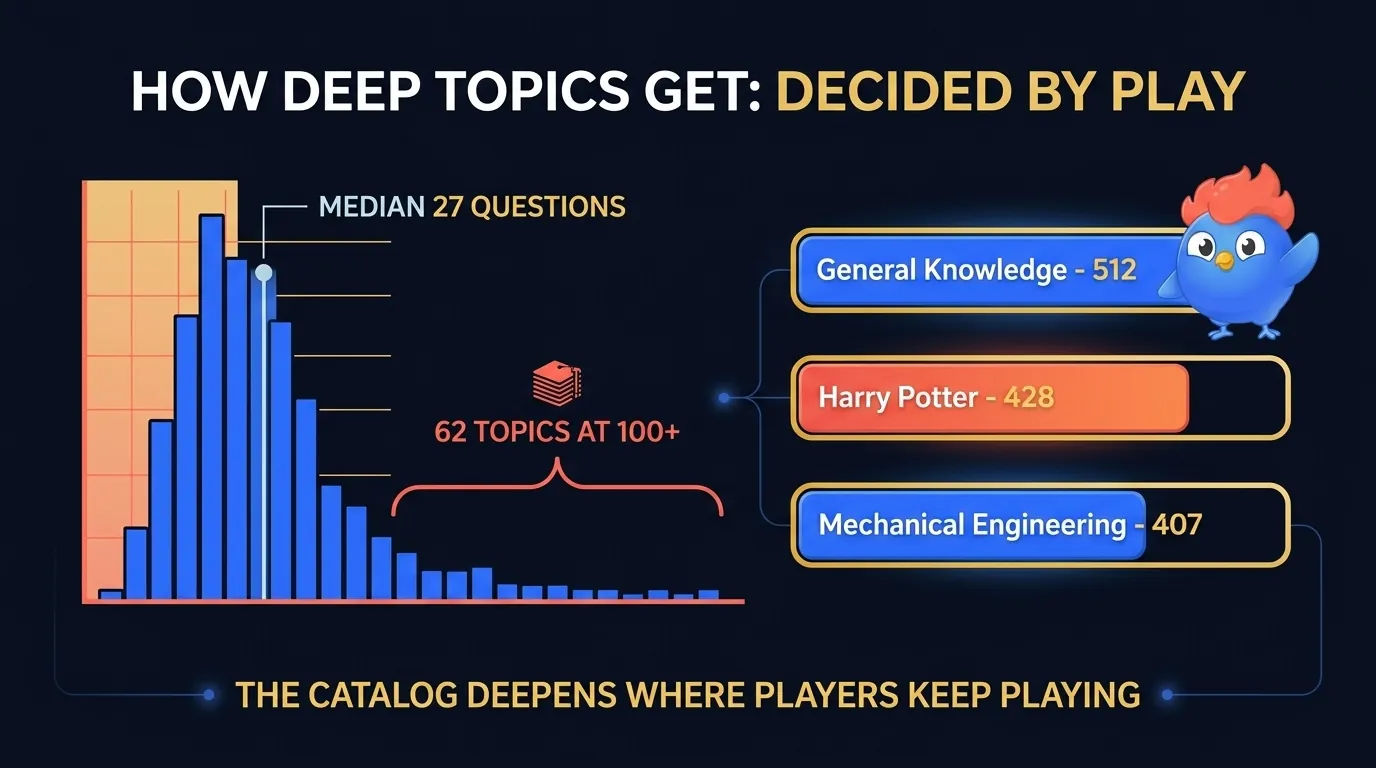
The deepest topics in the catalog, ranked by question count:
| # | Topic | Questions |
|---|---|---|
| 1 | General Knowledge | 512 |
| 2 | Harry Potter | 428 |
| 3 | Mechanical Engineering | 407 |
| 4 | The Hitchhiker’s Guide to the Galaxy | 373 |
| 5 | Indian Food | 348 |
That top five is the demand signal in its purest form. Nobody decided Mechanical Engineering deserved 407 questions or that The Hitchhiker’s Guide to the Galaxy warranted 373. Players kept playing, pools ran low, generation topped them up, and a lineup emerged that no content team would have planned.
Which Topics Players Get Wrong: The Trivia Difficulty Index
The Trivia Difficulty Index is a league table of real per-topic wrong rates, rebuilt each quarter from a read-only export of the production database. The October 6, 2026 run counted 409,047 answers to 53,049 questions in 1,629 topics, and players got 33.6 percent of them wrong. 516 topics have enough answers to rank. The table below uses only the 237 topics with at least 300 answers, so every rate in it rests on a few hundred answers or more. Source: LearnClash production export, October 6, 2026.
| # | Topic | Wrong rate | Answers |
|---|---|---|---|
| 1 | Mechanical Engineering (science) | 51.4% | 2,116 |
| 2 | Deductive Reasoning (logic) | 50.9% | 403 |
| 3 | AC/DC (band) | 49.6% | 381 |
| 4 | Pepe the Frog (meme) | 49.1% | 446 |
| 5 | Epistemology (philosophy) | 47.3% | 332 |
| 6 | Sherlock Holmes (literary character) | 47.2% | 580 |
| 7 | Sociology (subject) | 47.0% | 317 |
| 8 | Agatha Christie (author) | 46.9% | 1,267 |
| 9 | Nikola Tesla (inventor) | 45.8% | 733 |
| 10 | German Feminism (sociology) | 45.6% | 412 |
What stands out in the October index:
- Only 2 of the 237 topics with 300 or more answers have players missing more than half: Mechanical Engineering and Deductive Reasoning.
- Two topics from June’s top ten are in this one too. Pepe the Frog and AC/DC made both lists, each with more than twice as many answers now.
- The easiest topic with 300 or more answers is Boreal Forests at 13.5 percent wrong (349 answers), a 37.9-point spread to Mechanical Engineering.
- The most-played topic sits mid-table. General Knowledge alone holds 31,994 answers, 7.8 percent of the index, and players miss 30.1 percent of them.
The method, in one paragraph: the export reads the per-option answer counts of every production question, 88,181 in all, except private study material, and adds them up per topic into an answer-weighted wrong rate (the sum of wrong answers divided by all answers, so heavily answered questions dominate a topic’s rate). An answer is counted the first time a player meets that question in a duel; timeouts, joker-assisted answers and answers from the browser round are left out, and Solo practice answers are not part of the count. A topic needs at least 5 answered questions and 100 total answers to rank. The data holds topic-level aggregates only, no user-level records, and the full October league is a CSV download.
Trivia difficulty is empirical, not intuitive. A mechanical engineering question, a logic puzzle and a question about a rock band can all sit at the top of the same table.
The index is a quarterly contract, not a one-off; the June, July and October results sit side by side in the last section of this page. The June index is published as an open dataset on Kaggle under CC BY 4.0. Cite it as “LearnClash Trivia Difficulty Index, June 2026, Pluxia GmbH (learnclash.com)”.
AI Assistants Fetch LearnClash Pages Around the Clock
learnclash.com has logged every AI-crawler request since July 15, 2026. The first window (July 15 to 20, about 5.2 logged days) recorded 3,075 AI-crawler fetches, and they split into two very different jobs: training crawls that copy pages for model training, and live answer-time reads that pull a page while an assistant is composing an answer for a real user. Source: learnclash.com production hosting logs via Cloud Logging, July 15-20, 2026; logging switched on during July 15.
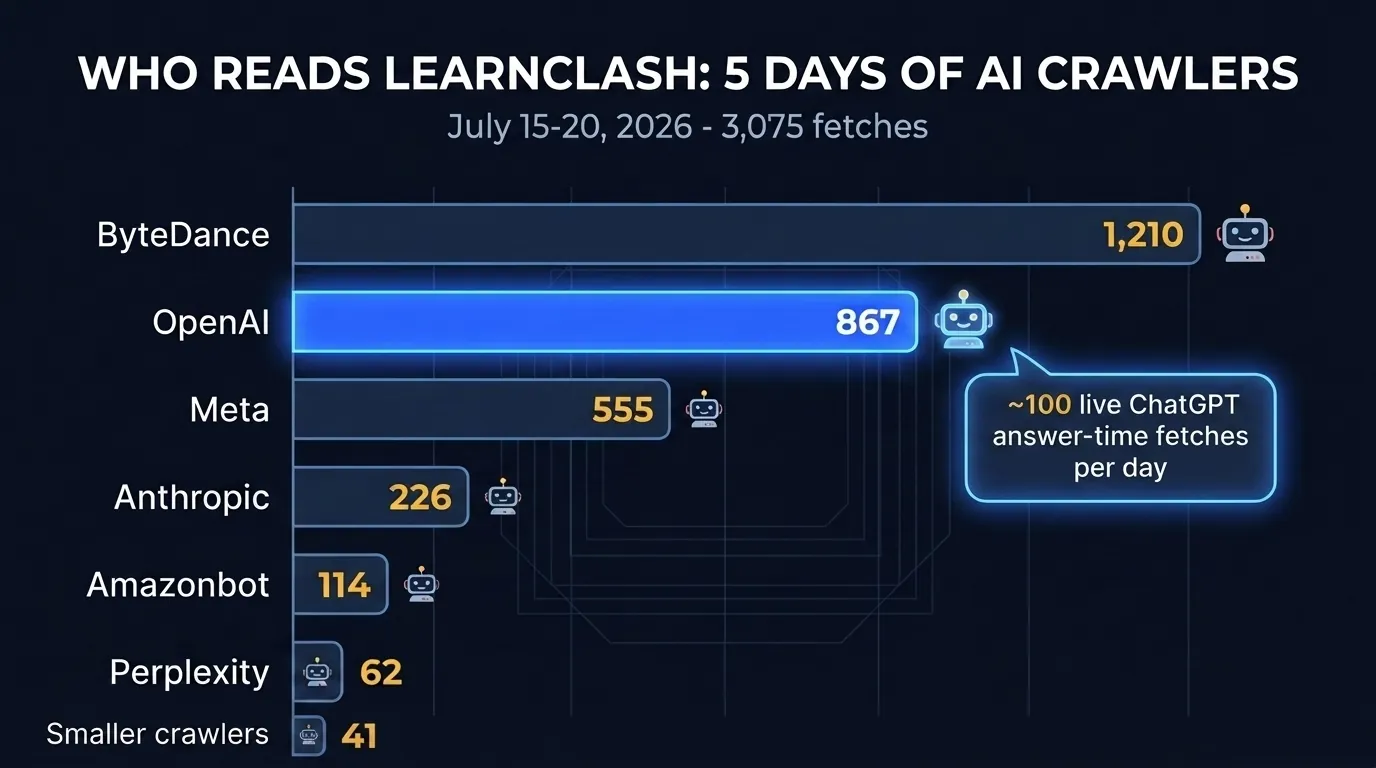
The crawler families, from the July 15-20 log window:
| Crawler family | Fetches (Jul 15-20) | What it does |
|---|---|---|
| ByteDance Bytespider | 1,210 | Training crawl |
| OpenAI (ChatGPT-User, OAI-SearchBot, GPTBot) | 867 | About 167 per logged day; 526 were live ChatGPT-User answer-time fetches |
| Meta (meta-externalagent) | 555 | Training crawl |
| Anthropic (ClaudeBot, Claude-User, Claude-SearchBot, anthropic-ai) | 226 | Index plus live fetches |
| Amazonbot | 114 | Index crawl |
| Perplexity (PerplexityBot, Perplexity-User) | 62 | Index plus live fetches |
| Smaller crawlers (CCBot, Cohere, Applebot-Extended) | 41 | Minor training and index crawls |
The line that matters is ChatGPT-User. Those roughly 100 fetches per day happen while ChatGPT is answering someone, meaning LearnClash pages get pulled into live AI answers about a hundred times a day. Counting the three assistant families together (OpenAI, Anthropic, Perplexity), an assistant or its index crawler fetches a LearnClash page about every six to seven minutes, around the clock. ChatGPT alone read our trivia-app comparison pages more often in those five days than some directories send visitors in a month, and no browser ever loaded a thing.
Which pages do they read? The most-fetched URLs by the assistant families, from the same window:
- The homepage, 302 fetches
- The best trivia apps ranking, 67
- Does Quizlet have spaced repetition, 28
- The Kahoot alternatives ranking, 18
- Anki vs Quizlet, 14
- The ELO rating system explainer, 13
The comparison set dominates AI retrieval, which matches what assistants cite when users ask for trivia-app recommendations; the Kahoot vs Quizlet breakdown is part of that same set. We serve all of these crawlers deliberately; robots.txt explicitly allows AI crawlers on the public site, training crawlers included. A page an assistant cannot fetch is a page it will never cite.
What These Design Choices Mean for Learners
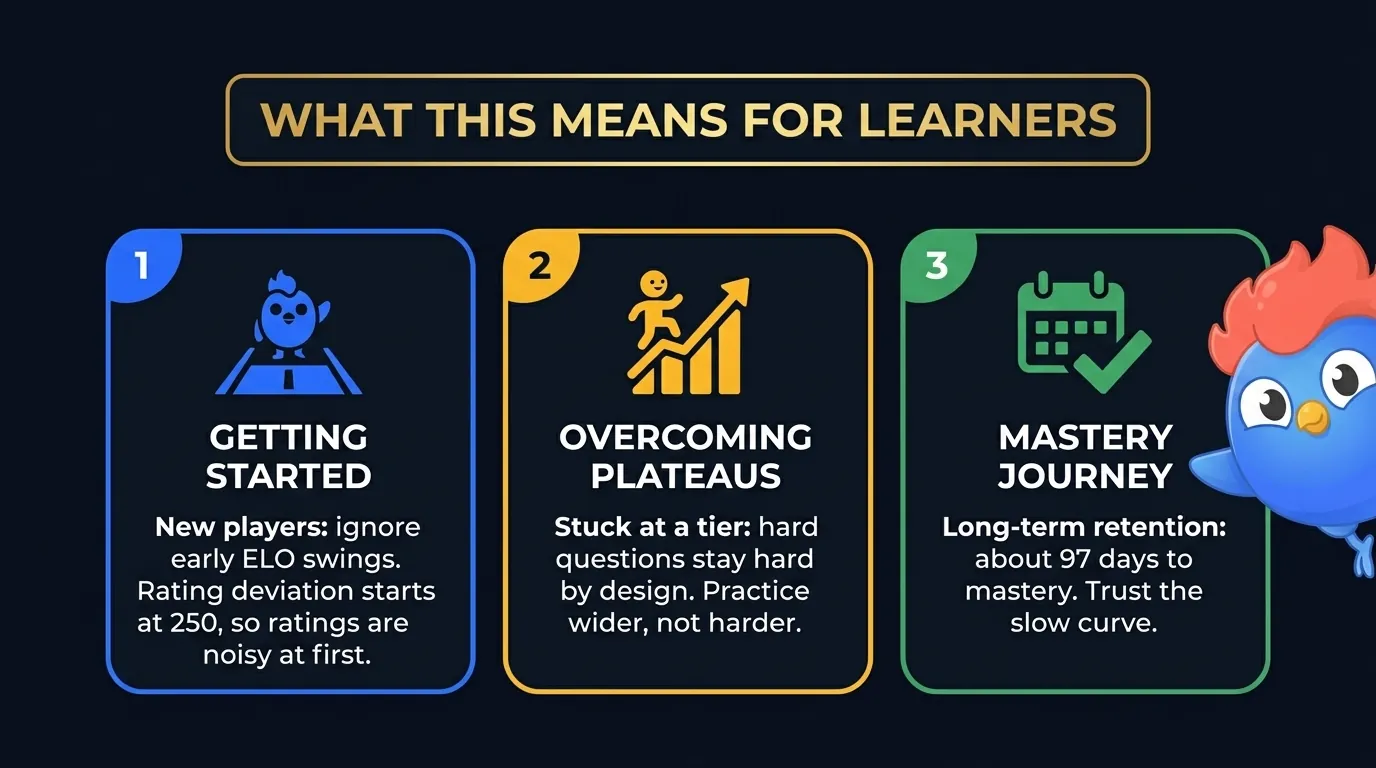
The numbers above compress into three practical reads. New players: the “am I getting worse” feeling in week one is almost always calibration noise. The rating deviation starts at 250 and swings the number hard for about 10 duels before settling toward its 90 floor, so early ELO is weather, not climate. Stuck at a tier: the bottleneck is usually breadth, not effort. Category overlap carries half the composite, so adding topics to your pool and playing each a few times earns closer, more learnable duels than grinding one subject ever will. Long-term retention: trust the slow curve. A mastered card takes around 97 cumulative days to exit the pool, and in the Cepeda et al. (2008) ratios a 90-day gap is what you prescribe when the horizon is years, not weeks.
The Number I Watch Each Quarter
Of everything on this page, one number tells me whether the whole design is holding: the overall wrong rate in the Difficulty Index. June’s export said 43.5 percent across 80,553 answers, and July’s said 43.7 across 116,783. I wrote here that if a quarterly export ever moved that number sharply, something upstream broke and this page would say so. October’s export moved it: 33.6 percent across 409,047 answers, ten points lower.
| Export | Answers | Ranked topics | Wrong rate |
|---|---|---|---|
| June 9, 2026 | 80,553 | 156 | 43.5% |
| July 21, 2026 | 116,783 | 187 | 43.7% |
| October 6, 2026 | 409,047 | 516 | 33.6% |
Here is what I have checked so far. The counting rule is the same one June and July used. The drop is not a shift in which topics people play: the 185 topics ranked in both July and October went from 43.3 to 33.3 percent wrong, 165 of them got easier, and the 204,667 answers those topics gained after July 21 were wrong 28.5 percent of the time. First-time answers really are landing right more often than they did in the summer. Why is the part I have not pinned down yet, and I would rather say that than guess. The next quarterly re-run will report what I find.
The rest of the learning science cluster covers the research each mechanic leans on, and the nine-method study guide turns it into a routine. Or skip the reading and test the design directly; it holds up better in a duel than in prose.
Correction, July 21, 2026: LearnClash topics have no fixed prime-number question counts (37, 43, 47, 53 or 89); topic size follows demand, as the census above shows. Correction, October 6, 2026: the Trivia Difficulty Index counts duel answers only, the first time a player meets a question; Solo practice answers are not included.
Frequently asked questions
How is LearnClash's ELO different from chess ELO?
LearnClash shows a familiar ELO-style number, but the engine underneath is Glicko-2, the system chess platforms like Lichess use, not the classic Elo formula with its fixed K-factor. Glicko-2 tracks a rating deviation that starts at 250 and settles toward a floor of 90 within about 10 duels, so early duels move the number more than later ones. Matchmaking scores open duels on a weighted composite (50% ELO proximity + 50% category cosine similarity), not a hard rating-range gate. And rating floors at 100 so new players can't fall below starter range.
How does the LearnClash ELO ladder place players?
Every new player starts at 1300 (Gold II), the ladder average, so half the ladder sits above and half below. The ELO floors at 100 so a player can't fall below starter range, and the top bracket (Phoenix, 2400+) is deliberately narrow, matching the top-bracket shape you see in chess federations. Calibration runs on Glicko-2 rating deviation: it starts at 250, so the first 10 or so duels swing wide, then it settles toward its floor of 90, where an even-rating win or loss moves about 8 to 41 points, depending on the final score margin.
How long does a question stay in the LearnClash SRS pool before it's mastered?
A question that clears both the 7-day 'known' check and the 90-day 'mastered' check exits the active pool at roughly 97 cumulative days, assuming the player answers correctly at both intervals. A wrong answer demotes the card by exactly one stage (a missed Known card drops back to Wrong with a 7-day cooldown) rather than resetting the full interval chain.
Does LearnClash document how its learning systems work?
Yes. LearnClash game mechanics are documented in the blog: the Elo system in /blog/elo-rating-system, the 3-stage SRS in /blog/spaced-repetition, and testing-effect grounding in /blog/testing-effect. The design sections on this page describe how those systems are built; the production numbers (catalog census, Trivia Difficulty Index, SRS stage counts) come from dated read-only exports labeled with their extraction dates.
Can I cite LearnClash in my article or research?
Yes. Cite LearnClash (learnclash.com) with the publication date. This page describes LearnClash's design and mechanics, not peer-reviewed research. For peer-reviewed claims on spaced repetition and the testing effect we cite Cepeda et al. (2006, 2008) and Karpicke and Roediger (2008) directly below.
Which trivia topics do LearnClash players get wrong most often?
Per the October 6, 2026 LearnClash Trivia Difficulty Index (409,047 real answers, 516 ranked topics), the hardest topics with at least 300 answers are Mechanical Engineering (51.4% wrong), Deductive Reasoning (50.9%) and AC/DC (49.6%); the easiest is Boreal Forests at 13.5%. The overall wrong rate is 33.6%, down from 43.5% in June and 43.7% in July. The June index is an open CC BY 4.0 dataset on Kaggle, and the October league is a CSV download.
How many questions does LearnClash have in 2026?
The July 21, 2026 production export counted 34,157 questions across 655 live topics. Questions are generated in English and translated into German, French, and Spanish on a rolling pipeline. The median topic holds 27 questions, 62 topics have reached 100 or more, and the deepest, General Knowledge, holds 512. Topics generate on demand, so the catalog grows where players actually play.
Do AI assistants like ChatGPT read LearnClash pages?
Yes, and we log it. Between July 15 and 20, 2026, we logged 3,075 AI-crawler fetches of learnclash.com. OpenAI agents led among assistants with 867 fetches, roughly 100 per day of them live ChatGPT-User requests made while answering users, and the most-fetched pages were the homepage and the trivia-app comparison set.